
Subagent guides usually arrive as a list of a dozen or so settings, each with a sensible tip attached. Keep the description sharp. Limit the tools. Pick the right model. Cap the turns. Scope the memory.
Read as a list it is forgettable, because a dozen independent tips is exactly the shape of advice nobody retains. Read as a group it turns out to be one idea with several dials, and it is an idea security people have been arguing for since the 1970s: grant the minimum capability the job requires, and nothing else.
Once you see the settings that way, the recommended defaults stop looking like tuning and start looking like a permission model that most teams are running wide open.
The one question
Every setting on a subagent answers a version of the same question:
| Setting | Actually asking |
|---|---|
| Tool allowlist | What may this agent do |
permissionMode | What may it do without asking |
| MCP server scope | What external systems may it reach |
| Memory scope | What may it remember between runs |
| Preloaded skills | What instructions occupy its context by default |
| Model choice | How much capability does this job justify |
maxTurns | How long may it run unsupervised |
| Description | When may it be invoked at all |
Written like that, the guidance stops being a list of tips. It is an access-control matrix, and every generous default is a privilege you granted without deciding to.
The reason this matters more for subagents than for the main loop is delegation. A subagent runs with less oversight, on a task you are not watching, often in parallel with others. That is exactly the situation where over-granted permission stops being theoretical.
Where the defaults are wrong
Three of these dials are worth arguing about, because the defaults are convenient and expensive.
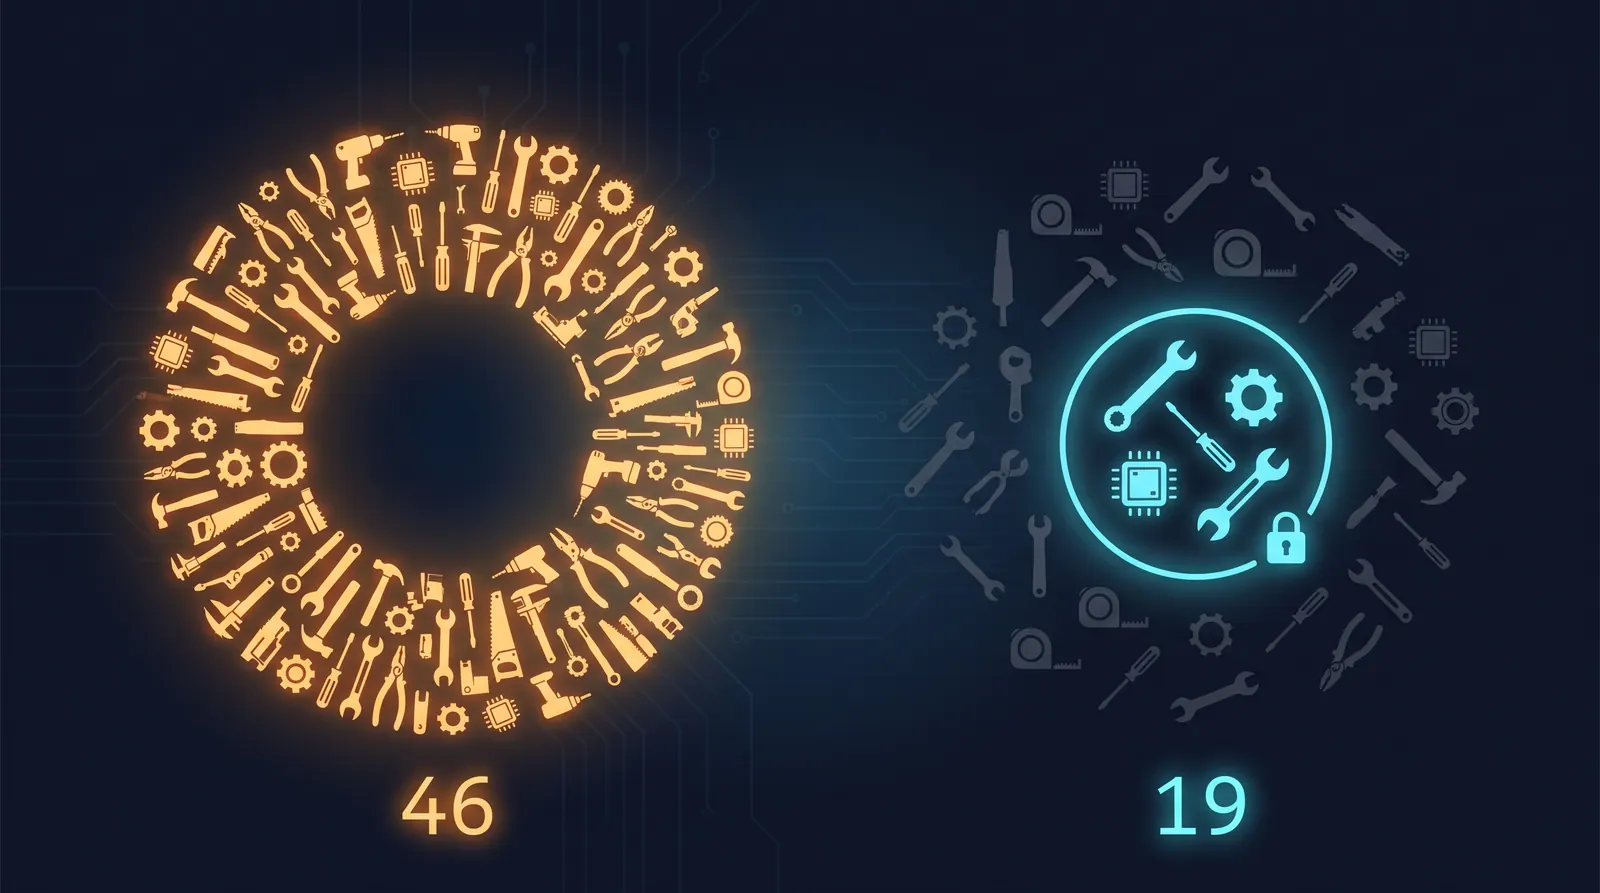
The tool allowlist is the important one, for two reasons at once. The obvious one is blast radius: an agent that only reads files cannot delete any. The less obvious one is quality. Every tool definition sits in the context window and competes for the model’s attention, and the failure mode is measurable — a small model given all 46 tools of a benchmark failed at it and passed when given 19, with the context well within its limit either way. That is context confusion, and the allowlist is the direct fix.
So the tool list is doing double duty. Narrowing it is a security decision and an accuracy decision, which is unusual and makes it the first knob to touch.
Model choice is a cost decision people make once and never revisit. A subagent that greps a codebase and returns matching paths does not need your most capable model. A subagent that reads a design document and decides whether an implementation satisfies it does. Mixing tiers within one system is normal and correct, and the pattern that works is expensive-model-decides, cheap-model-fetches.
maxTurns is the one that reads as pedantic and is not. An agent without a turn cap has no termination guarantee, and “it usually finishes” is not a guarantee. This is the same hazard as an unbounded retry loop or a while with a condition that depends on a remote system. Nobody would ship the second; the first gets shipped constantly because the failure is a slow drain rather than a crash.
The description is a routing decision, not documentation
The setting most often written as an afterthought is the one that determines whether any of the rest applies.
A subagent’s description is what the parent reads when deciding whether to delegate. It is not a comment for humans and it is not a summary of what the agent contains. It is the trigger condition, and it is doing the same job as a tool description: telling the caller when to reach for this, not merely what it is.
The practical difference is stark. “Code reviewer” describes a thing. “Reviews a diff for correctness and security issues, after the change is complete and before it is proposed” describes an occasion. The first gets invoked at random moments; the second gets invoked when it should be.
The failure mode when several agents have vague descriptions is worth naming, because it looks like a model problem and is not: the parent cannot tell which specialist to call, so it picks by vocabulary overlap and gets it wrong. Sharpening two descriptions fixes what looks like a reasoning failure.
What delegation actually costs
There is a prior question the setting lists skip, and it is the one that decides whether to configure a subagent at all.
Each delegation is a fresh context. The subagent re-establishes what it needs to know, does the work, and returns a summary — and the parent then reads that summary, which is a second act of comprehension over material it did not see produced. That round trip is the cost, and it is charged whether or not the delegation was necessary.
Which gives a rule that predates any of this tooling: delegate for isolation, not for tidiness. A subagent earns its cost when it keeps a large volume of intermediate work out of the parent’s context — a wide file search, a long exploratory read, anything where the useful output is a fraction of what was consumed to produce it. A subagent that reads one file and reports what it says has moved a cheap operation into an expensive one and made it harder to debug.
This is the same arithmetic as the supervisor pattern in multi-agent graphs: coordination is not free, and it is worth paying for only when it buys real isolation or a real decision.
Memory and MCP are the sharp edges
Two settings deserve more caution than they usually get, because they extend past the run.
Memory scope. A subagent with access to shared memory can write things that later runs read as fact. If the agent is wrong once and records it, you have manufactured context poisoning with a persistence layer — a bad fact that survives the session that produced it and gets re-read by everything afterwards. Read access is cheap to grant; write access should be narrow and, for anything consequential, reviewed.
MCP server scope. Connecting a server to every agent because one needs it means every agent carries its tool definitions in context and can call them. The context cost is real, and so is the reach: an agent with database access has database access on every task, including the ones where that made no sense.
Both follow the same rule as the tool allowlist, which is why the whole set collapses into one principle rather than a dozen.
A configuration order that works
- Start from nothing and add. Empty tool list, no MCP servers, no memory, then grant what the task provably needs. Starting from the full set and trimming leaves permissions nobody chose.
- Write the description as a trigger. When should this be called, in what situation, at what point in a workflow. If two agents’ descriptions could both match a request, one of them is wrong.
- Cap the turns. Whatever number feels generous, then treat hitting it as a signal rather than a nuisance.
- Pick the model per job, and revisit it. Fetching and searching do not need the tier that reasoning needs.
- Ask whether to delegate at all. If the subagent will consume little and return most of it, do the work inline.
- Grant memory write access last, and narrowly. It is the only setting whose mistakes outlive the run.
None of this is specific to any one tool. It is the permission model any system gets when several components act on shared resources with partial autonomy, and it has a well-tested answer. The novelty is only that the components are now agents, and that the defaults ship wide open because narrow defaults would look broken in a demo.