
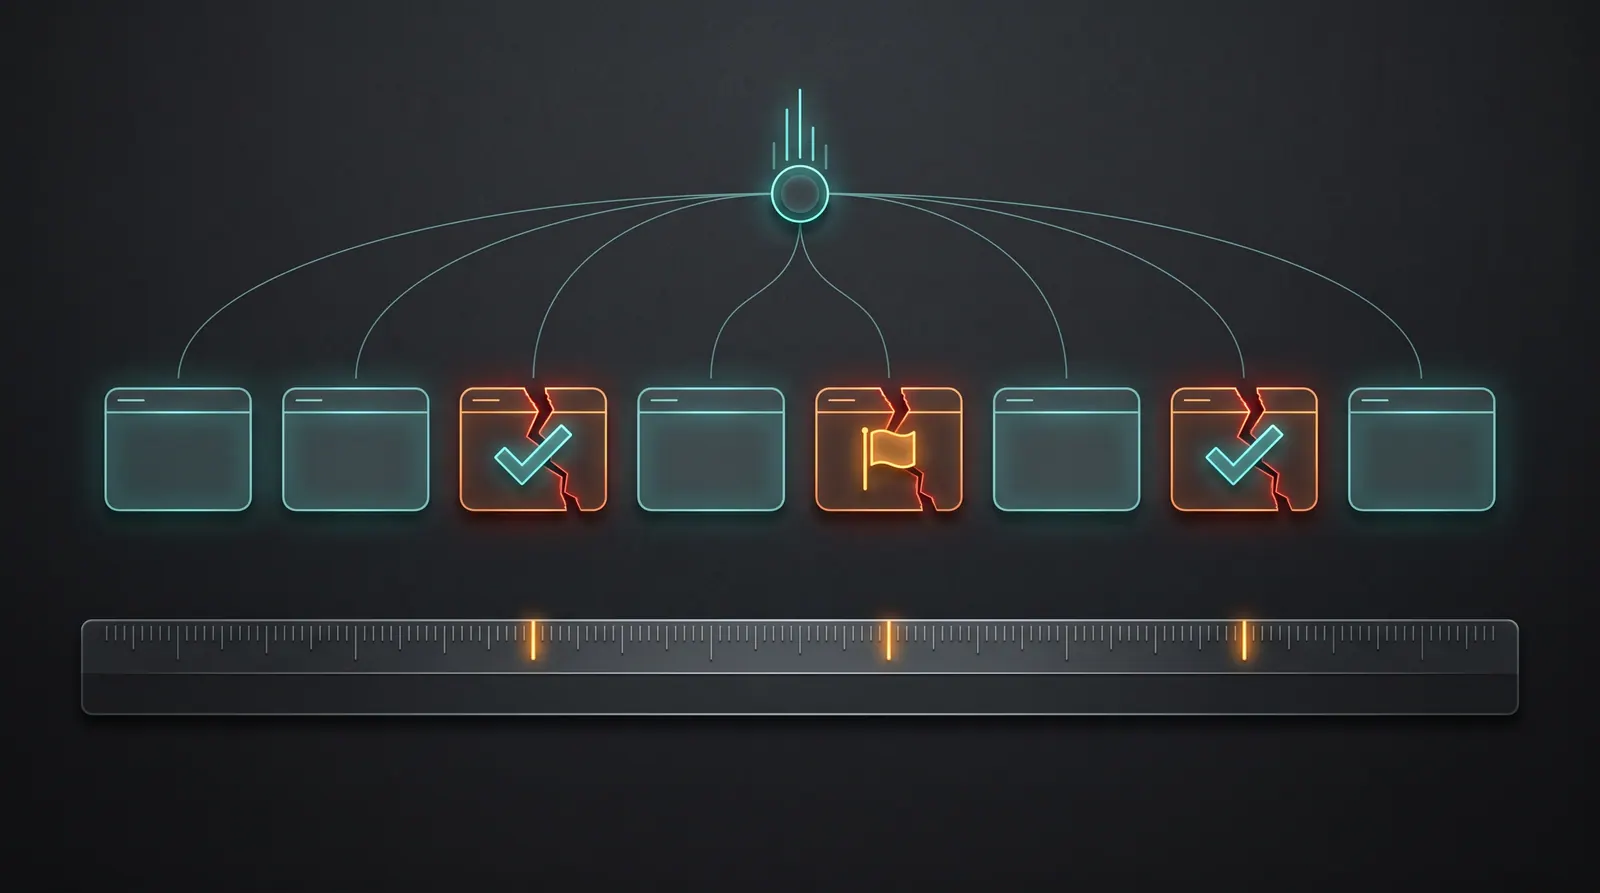
There is a pattern going around for browser testing: let a fast model choose the next probe, run it with Playwright, then ask the model whether the result broke a requirement. Two small calls per step, answered in a fraction of a second, and the page does the rest.
The pattern is easy to like. It is also easy to demo, because a demo with deliberate bugs makes the verdicts look sharp. I wanted to know what survives when I build one myself, add a baseline, and keep the bugs I planted written down.
So I built it, small. Eight probes, three real bugs, five correct behaviours that look suspicious.
One thing first, because it decides how to read everything below. This is not a test of any hosted model. The request shape comes from TypeSafe’s System One API, where a call carries a state and named questions of type choice, score or noul (API introduction). I pointed it at a local server that speaks the same API. The response named the model laya-rl-agent, a small model running on CPU. Whatever follows is about this loop and this model on this prompt. It says nothing about how a larger hosted model would do.
The loop
Three parts, and only one of them is a model.
Playwright drives a page and reads it back. A controller holds the list of probes, decides which are currently possible, and keeps history. The decision API does two jobs: pick the next probe from the menu, then say whether the observed result violates a requirement.
The model never sees the browser. It sees text the controller builds:
async function ask(state, questions) {
  const r = await fetch(URL, {
    method: "POST",
    headers: { "content-type": "application/json", Authorization: `Bearer ${KEY}` },
    body: JSON.stringify({ state, questions }),
  });
  return (await r.json()).answers;
}

const verdict = {
  type: "choice",
  instructions: "Does this action and its observed result provide direct evidence of a requirement violation? Judge only this action and the before/after change.",
  criteria: {
    bug: "Direct observed violation of the requirement.",
    ok: "Observed outcome is consistent with the requirement.",
    uncertain: "Insufficient evidence or ambiguous outcome.",
  },
};

const before = await observe(page);   // total, quantities, notice
await probe.act(page);
const after = await observe(page);
const { verdict: v } = await ask(
  { requirement: probe.req, action: probe.id, before, after },
  { verdict },
);
The choice answer comes back with a label and a probability for each option, so code can read it directly instead of parsing prose. That part works as advertised.
The fixture
A single HTML page, set with page.setContent: a lamp at $80, headphones at $50, a coupon field, an email field, a checkout button. I wrote the bugs, so the ground truth is not in question.
| Probe | Requirement | Truth |
|---|---|---|
coupon_first | SUMMER10 takes 10% off once | ok |
coupon_again | The second application must not compound | bug (80 → 72 → 64.80) |
coupon_invalid | Other codes change nothing | ok |
qty_negative | Quantities must be positive | bug (total becomes −20) |
qty_zero | Reject zero | ok |
qty_999 | No upper limit is specified | ok (total $50,030) |
email_valid | Reject malformed emails | ok |
email_malformed | Reject malformed emails | bug (order placed) |
Three of the correct rows are traps on purpose: a huge quantity, an invalid coupon, a legitimate email. A judge that flags anything odd would fail them.
Result one: the judge
Each probe ran five times on a fresh page. The answers did not change between repeats, so the 40 verdicts are really eight decisions made five times each.
probe            truth  got   margin
coupon_first     ok     ok    0.138
coupon_again     bug    ok    0.179
coupon_invalid   ok     ok    0.410
qty_negative     bug    ok    0.403
qty_zero         ok     ok    0.596
qty_999          ok     ok    0.377
email_valid      ok     ok    0.456
email_malformed  bug    bug   0.184
Six of eight right. It passed every trap and found one of three bugs. It called the compounded coupon and the −20 total ok.
margin is the gap between the top probability and the runner-up. It tells you how sure the model sounded, which is a different thing from whether it was right.
Result two: confidence did not help
The obvious fix for a shaky judge is an abstention rule: below some margin, say “uncertain” and send it to a person. I tried it on these numbers.
abstain below margin 0.2: answered 25/40, correct 20At 0.2 the rule drops three probes: coupon_first (correct), email_malformed (correct, and the only bug found) and coupon_again (wrong). The other wrong answer, qty_negative, sits at 0.403 and survives.
So the threshold removed two right answers and one wrong one, and the most confident miss went straight through. With eight data points I will not claim a calibration curve. What I can say is that nothing here justified treating the margin as a measure of correctness. If you adopt an abstention rule, measure it against labelled cases first. The same discipline applies to any judge: a number from a model is an instrument reading until someone calibrates it.
Result three: did it choose better than chance?
The other half of the pattern is exploration. Instead of a fixed script, the model picks the next probe from those currently possible. The claim is that it picks the informative ones.
To test it I let the model choose until the menu ran out, with the probes’ real outcomes feeding history, then counted how many probes it took to hit all three bugs. Baselines: the menu’s own order, and 20,000 random orders that respect the dependency (the repeat coupon needs the first one).
model:   coupon_first > coupon_again > coupon_invalid > qty_zero > qty_negative > qty_999 > email_valid > email_malformed
         all 3 bugs found after 8 of 8 probes  (same order in 3 runs)
menu order: 8
random:  mean 7.35, median 8, p90 8
The model’s order was the menu order in all three runs, and it needed all eight probes. Random order needed 7.35 on average. That is no advantage. The obvious suspect is position bias, so I shuffled the menu twelve times and asked for the first choice. It picked the first listed option twice, and coupon_first nine times. It was drawn to a particular probe, not to a position, and it is not clear that probe was the informative one.
With eight probes this is a toy, and the random baseline has little room to lose. A bigger menu is the fair test. Still, “the model chose a good order” is a claim that needs the baseline beside it, and this run gives no support for it.
What deterministic code did
Here is the same fixture checked by three comparisons I wrote after the bugs were known:
const ORACLE = {
  coupon_again:    (b, a) => a.total !== b.total,                   // second application must not change the total
  qty_negative:    (b, a) => a.qty.headphones !== b.qty.headphones, // a rejected value must not stick
  email_malformed: (b, a) => a.notice === "Order placed",
};
oracle right 8 / 8Eight of eight, no model, no network call. This is not a fair fight and I will not dress it up as one. The oracle was written by the person who planted the bugs, so it knows exactly what to look for. Its value is narrower: when the expected result is precise (a total, a stored quantity, a status string) an assertion is cheaper, faster and exact. Computing 10% off does not need a probability.
Where a model belongs in this loop
The result points at a division of labour rather than a verdict on models:
- Exact expectations: code. Totals, stored values, status codes, anything with a right answer you can write down.
- Fuzzy outcomes: a model, with its disagreement visible. “Does this error message make sense to a customer?”, “Is this page obviously broken?” These have no one-line oracle. If the margin is thin, show it, because a bare label hides how close the call was.
- Exploration: a model only if you measure it against order and chance. Otherwise a prioritised, dependency-aware fixed list is simpler and no worse on this evidence.
The same split shows up in driving a browser with an agent: the model proposes, the specification decides what correct means.
Where this breaks
- One model, one prompt. A different model or a better instruction could change every number above. A prompt that also supplied the expected arithmetic would likely fix
coupon_again, but at that point you have written the assertion. - Eight probes. Too few to estimate accuracy. The five repeats confirmed determinism, not sample size.
- The fixture is mine. Bugs and oracles came from the same head. Real applications contain bugs nobody planted.
- No hosted model was tested. If you want to know how a larger model does, run this loop against it. The fixture and the baselines are the reusable part; the verdicts are not.
- Latency is machine-dependent. Local calls took a median of 252 ms in one run and 390 ms in another on the same CPU while other work ran. That is a property of this setup.
What to take from it
Before trusting a model in a test loop, give it something with a known answer and a baseline to beat. If it finds the planted bugs, you have a reason to widen its job. If it passes the traps and misses the bugs, as this one did, you have learned that “no false alarms” and “finds problems” are two different properties, and a green dashboard only proves the first.