
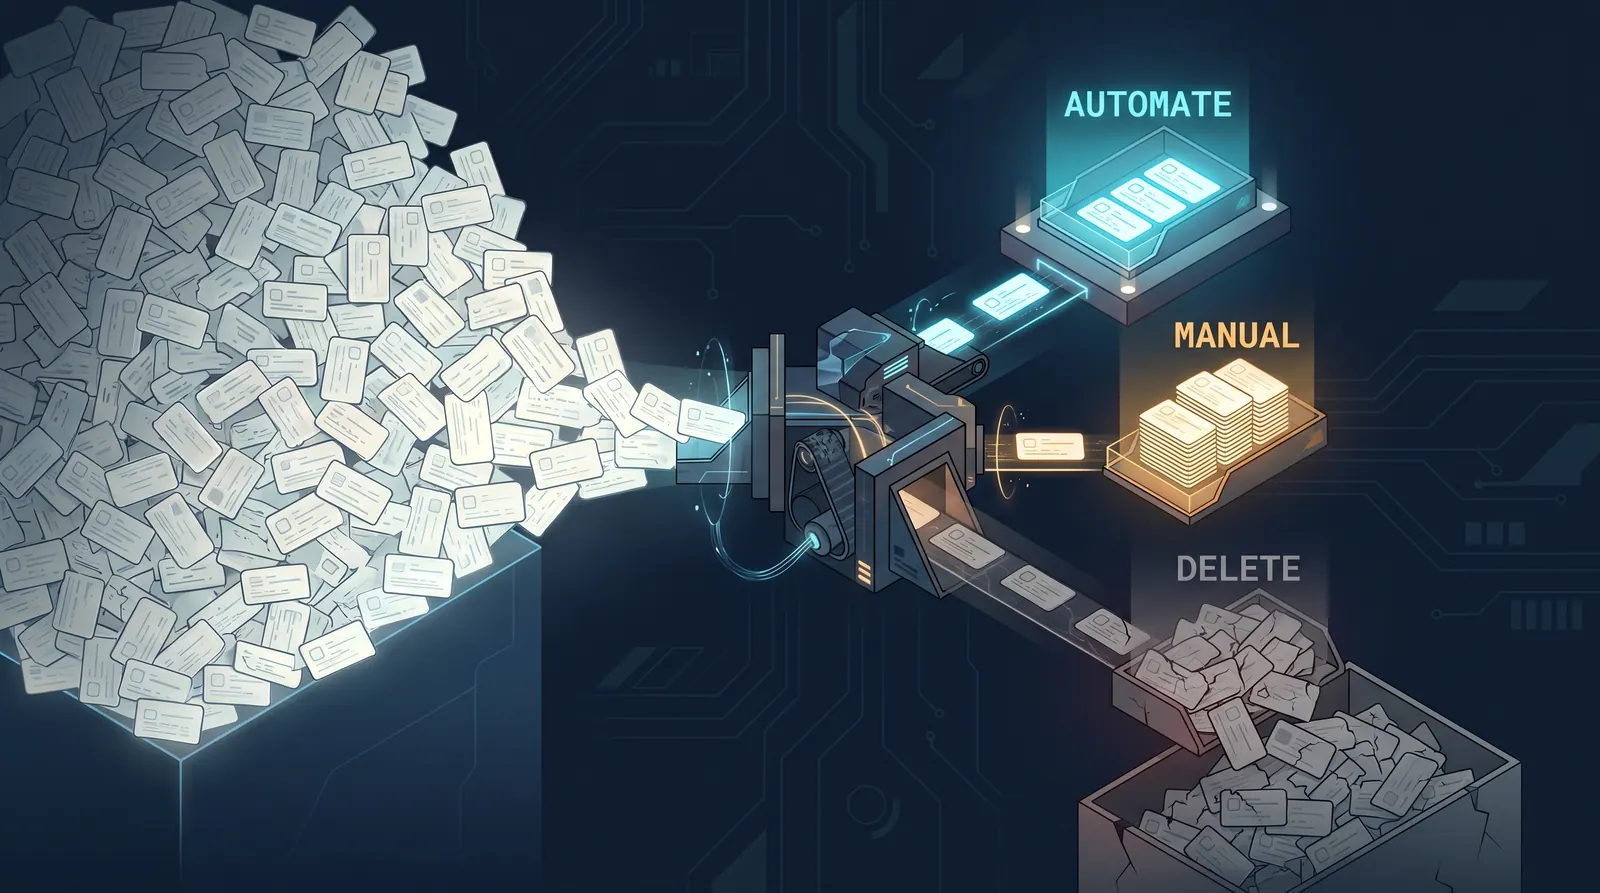
Automation suites do not usually die from bad tooling. They die from accumulation: hundreds of tests nobody decided to write, each added because somebody had a ticket and automating it seemed better than not, maintained forever by people who inherited them and cannot tell which ones still matter.
The framework is rarely the problem, and neither is the framework choice everyone spends weeks on. The problem is that selection was never a decision. Anything testable got automated, so the suite grew to the size of the application rather than to the size of the risk.
Two questions fix more than any tooling change. What is worth automating, and who gets to say no.
The selection rule
There is a version of this that fits on one line and holds up under pressure:
Automate a test when the cost of running it manually, times how often you will need it, exceeds the cost of writing and maintaining it.
The trap is that teams estimate the first half and ignore the second. Writing a test is a bounded, visible cost. Maintaining it is unbounded, invisible, and paid by someone else later — usually by whoever is on call when it goes red for the fourth time on an unrelated change.
Applied honestly, the rule sorts most candidates quickly:
| Automate | Because |
|---|---|
| Core paths a release cannot ship without | Run every build, forever; maintenance is trivially justified |
| Regression around a bug that reached production | Highest value per test in the whole suite |
| Data-integrity and permission checks | Failures are expensive and silent, and humans check them badly |
| Anything you have manually verified more than three times | You have already paid for it in labour |
| Leave manual | Because |
|---|---|
| Exploratory testing | The value is in the unscripted deviation, which automation removes by definition |
| Features still changing weekly | The test will be rewritten before it catches anything |
| One-off migrations and launches | Runs once; automation never amortises |
| Anything needing aesthetic or usability judgement | The assertion you would write is not the thing you care about |
| Rare paths that are cheap to check by hand | The maintenance outweighs the saving |
That last row is where suites bloat. A test for a path that runs twice a year, is cheap to verify manually, and breaks on every UI refactor is a net loss — and it will survive for years because deleting a test feels like reducing coverage.
Coverage is not the goal, and it never was
The number that drives most automation programmes is the one that measures the least.
Coverage tells you how much of the code was exercised. It does not tell you whether the assertions were meaningful, whether the paths that matter were among them, or whether a failure would be noticed. A suite at 80% coverage where the assertions are shallow is worse than one at 40% that checks the things that would actually hurt, because the first one produces confidence and the second one produces information.
Better questions to steer by:
- When something breaks in production, does a test go red? If not, coverage is decorative.
- When a test goes red, does anyone believe it? A suite people rerun to get green has a detection rate near zero regardless of its number.
- How long does the suite take, and how long since anyone deleted anything from it? Suites only ever grow unless someone is given permission to prune.
That third one is the one nobody owns, which brings us to the other half.
QA owns the bar and not the switch
Here is the structural problem underneath most quality conversations, and it is rarely stated plainly.
The people who can best judge whether something is ready to ship usually cannot decide whether it ships. Release decisions live with engineering managers or product, under delivery pressure that quality signals compete against. So QA reports a risk, someone else weighs it against a date, and the result is that quality is an opinion offered upward rather than a constraint enforced sideways.
That arrangement produces a predictable pathology. If the bar is advisory, it gets waived under pressure. If it gets waived often enough, people stop investing in the signal that keeps getting waived, and the suite decays into ceremony.
The fix is not to hand QA a veto, which does not survive contact with any real business. It is to convert judgement into pre-agreed policy while nobody is under pressure:
- Decide in advance which failure classes block, and write it down. Contract breaks, auth regressions, data integrity — agreed when the room is calm, not argued at 6pm on release day.
- Everything else produces a documented, owned risk acceptance. Not a blocked release: a named person, a written reason, a ticket.
- Track how often it happens. A pattern of overrides on the same class of failure is data about the bar, and it means either the bar is wrong or something needs fixing.
The important move is that the argument happens once, in advance, rather than every release under time pressure. That is the same principle as deciding which failures block before you need to know — a policy decided in advance is a decision, and a policy decided during an incident is a negotiation.
Maintenance is the whole cost
The part every strategy document underestimates.
A test suite is not an asset that appreciates. It is a codebase with no users, which means nobody notices when it rots, and it tracks a moving target, which means it rots continuously. Every UI change, every schema migration, every refactor pays a tax in test updates, and that tax scales with suite size rather than with suite value.
Three practices keep it survivable, and none of them are about frameworks:
Quarantine flaky tests immediately, and treat the quarantine as a queue. A flaky test left in the main run teaches the team to ignore red, which is the single most expensive habit a suite can create. Out of the run, into a tracked list, fixed or deleted within a sprint.
Delete on a schedule. Someone should be allowed, and expected, to remove tests that no longer earn their maintenance. This never happens spontaneously because deleting a test looks like a step backwards and nobody gets credit for it.
Make the failure message do the work. A red test whose output requires ten minutes of investigation to interpret costs ten minutes every time it fires. Time invested in clear assertions and useful failure output is repaid on every single run, and it is the cheapest performance improvement available.
What to do on Monday
- Pick ten tests at random and ask what each would catch. If you cannot name a realistic failure for one, it is a deletion candidate. This exercise is uncomfortable and usually productive.
- Sort the backlog with the selection rule before writing anything new. Cost of manual, times frequency, against write-plus-maintain. Say no out loud to at least one thing.
- Agree the blocking failure classes with whoever owns the release, this week. In writing, while nobody is shipping.
- Quarantine every currently-flaky test today. Then fix or delete them within the sprint, and do not let the list grow.
- Book a recurring hour for deletion. It will feel unproductive and it is the thing that keeps the suite fast enough to be believed.
The strategy that survives is not the one with the best framework or the highest coverage. It is the one where somebody decided what not to automate, wrote down which failures actually stop a release, and is allowed to delete things. Everything else is a suite growing until it is too slow to run and too fragile to trust.