
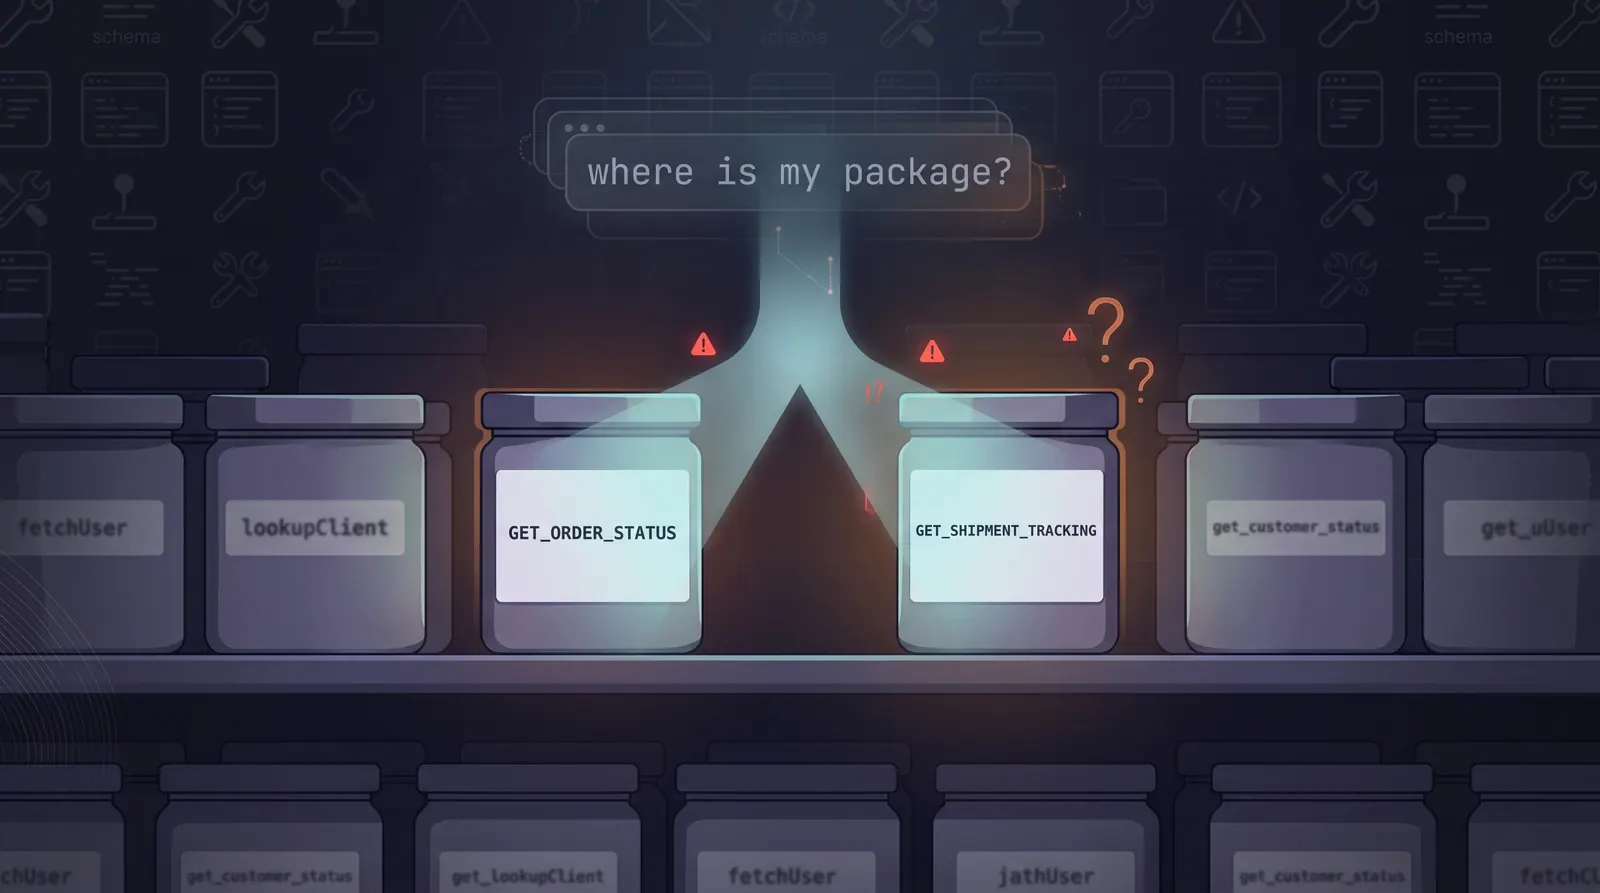
An agent with thirty tools calls the wrong one. It had get_order_status and get_shipment_tracking available, the user asked where their package was, and it picked the first. Both are plausible. One is right.
The instinctive read is that the model reasoned badly, so the instinctive fix is a better prompt — a system message explaining when to use which, maybe a worked example or two. That works occasionally, does nothing often, and the reason it does nothing is that the diagnosis was wrong.
The model is not reasoning over a menu. It is matching a query against a set of text descriptions all sitting in the same context, competing for the same attention. That is retrieval, and once you name it correctly the effective fixes stop being prompt fixes and start being indexing fixes.
What the model actually has
There is no tool registry the model consults. There is no lookup, no dispatch table, no structured choice.
Every tool you expose is serialised into the context as text: a name, a description, a parameter schema. The model reads all of it alongside the user’s message and produces the most probable continuation. When it emits get_order_status, that is not the output of a decision procedure over candidates. It is the token sequence that best matched, given everything in the window.
Two consequences follow immediately, and both are counter-intuitive if you are thinking about reasoning.
Similarity between tools directly hurts you. Two tools whose descriptions overlap semantically compete, and the competition is a property of the text, not of the model’s understanding of your domain. get_order_status and get_shipment_tracking both contain the shape of “look up where a customer’s thing is”. The model is not confused about your business. It is looking at two nearly identical index entries.
Count hurts you non-linearly. Accuracy does not degrade gently as you add tools; it holds and then falls off, and it falls faster when the added tools are semantically near their neighbours. The clearest published demonstration is a model that failed a benchmark when given all 46 of its tools and passed the same benchmark given 19, with the context well inside its limit either way. Nothing was truncated. The signal was diluted, which is a different failure and it is the same mechanism that degrades a long context generally.
So “the model should have known” is the wrong frame. It knew as much as the text told it, and the text told it two things that looked alike.
The five failure modes, and which fix each one
Read as retrieval, the failures sort cleanly, and each sorts to a different intervention. This matters because teams typically apply one fix to all five and conclude the technique does not work.
| Failure | What is actually wrong | The fix |
|---|---|---|
| Intent ambiguity | The query genuinely does not determine one tool | Clarify with the user, or route through a disambiguation step |
| Schema overlap | Two entries in the index describe the same region | Rewrite boundaries, or merge the tools |
| Surface overload | Too many candidates for the signal to separate | Cut the exposed set; consolidate granular tools |
| Naming drift | fetchUser, get_customer, lookupClient in one registry | Impose one convention; rename |
| Flat namespace | Thirty peers with no grouping | Group by domain so competition is local |
The one worth dwelling on is schema overlap, because the fix is the least obvious. When two tools keep getting confused, the reflex is to describe each one better. Often the right move is to notice they should be one tool with a parameter. get_order_status and get_shipment_tracking may well be get_order(include_tracking: bool), and now there is nothing to confuse. Backend complexity is unaffected — the consolidated tool routes internally. The model’s decision space shrank by one hard choice.
That inverts the usual instinct toward small, single-purpose functions. Good design for a human caller reading your API is not the same as good design for a caller doing fuzzy matching over descriptions.
Write descriptions as boundaries, not summaries
The single highest-yield change, and it takes an afternoon.
Most tool descriptions summarise what the tool does. What the model needs is when to use this one rather than the neighbour it keeps getting confused with. A description that never mentions its neighbours cannot separate itself from them.
Compare:
get_order_status— Returns the status of an order.
against:
get_order_status— Current fulfilment state of an order (placed, picked, shipped, delivered). Use for “where is my order” and “has it shipped”. Not for carrier-level scan events or delivery estimates; useget_shipment_trackingfor those.
The second is doing retrieval work. It names the queries it should win, and it explicitly cedes the queries it should lose. Negative statements are doing most of the work, and they are almost always absent, because writing “not for X” feels like an odd thing to put in documentation.
This is the same job a subagent description does when the parent decides whether to delegate: the text is not documentation, it is the trigger condition, and vague trigger conditions produce misrouting that looks like a reasoning failure.
Cut the candidate set
The other high-yield lever, and the one people resist because it feels like removing capability.
Every tool in context has a cost even when unused: it occupies tokens and it competes. A tool that is relevant to two percent of requests is paying rent on the other ninety-eight, and the rent is paid in the accuracy of every other selection.
Three ways to shrink the set, in increasing order of effort:
- Remove what is not being called. Instrument, look at a month of logs, delete the ones at zero. This is free and it is usually available.
- Consolidate. Six granular endpoints become one parameterised tool. The model chooses once instead of six times.
- Select dynamically. Classify the request first, expose only the relevant domain’s tools for that turn. More machinery, and the right answer once you have genuinely many tools.
The third is the one to reach for last, because it introduces a classification step that can itself be wrong, and a routing bug is harder to see than a tool-selection bug.
Measure it, because you can
Here is what makes tool selection unusually tractable compared to most agent quality problems: it has a single correct answer that a human can label in seconds.
Which means the eval is cheap and almost nobody builds it. Collect a hundred real requests. For each, write down which tool should have been called. Run them, compare, and put the results in a matrix of expected tool against selected tool.
The off-diagonal cells are the entire diagnosis. A dense cluster between two tools means schema overlap, and you now know exactly which pair to rewrite. Errors scattered evenly means overload. Errors concentrated on one intent means that intent is ambiguous and needs disambiguation rather than better descriptions.
You get all of this from a hundred labelled examples, no judge model, no subjective scoring, and no uncertainty about whether the grader itself is accurate — the check is exact string equality on a tool name. It is the easiest eval in the entire agent stack and it is the one most teams are missing.
Rerun it whenever the tool set changes. Adding a tool changes the accuracy of the tools already there, which is the least intuitive property in this whole area and the one that catches people.
The order to work in
- Build the confusion matrix first. A hundred labelled requests. Without it you are guessing which of the five failures you have.
- Delete unused tools. Free, immediate, and it improves everything else.
- Rewrite descriptions with explicit boundaries, including what each tool is not for. Target the pairs the matrix flagged.
- Merge the pairs that keep colliding. Two confusable tools are often one tool with a flag.
- Group by domain once the flat list exceeds what one screen holds comfortably.
- Only then consider dynamic selection, and treat its classifier as a component that needs its own measurement.
The reframe is the useful part. Reasoning problems get attacked with prompts and bigger models, and tool selection resists both. Retrieval problems get attacked by shrinking the candidate set and sharpening the index, and tool selection responds to both immediately.