
The technique fits in a sentence. Put your payloads in an array, loop the array, run the same assertions against each one. In Playwright it is a for loop around a test() call and it takes about four lines.
It is genuinely good practice, and the reason usually given for it is wrong in a way that quietly costs you.
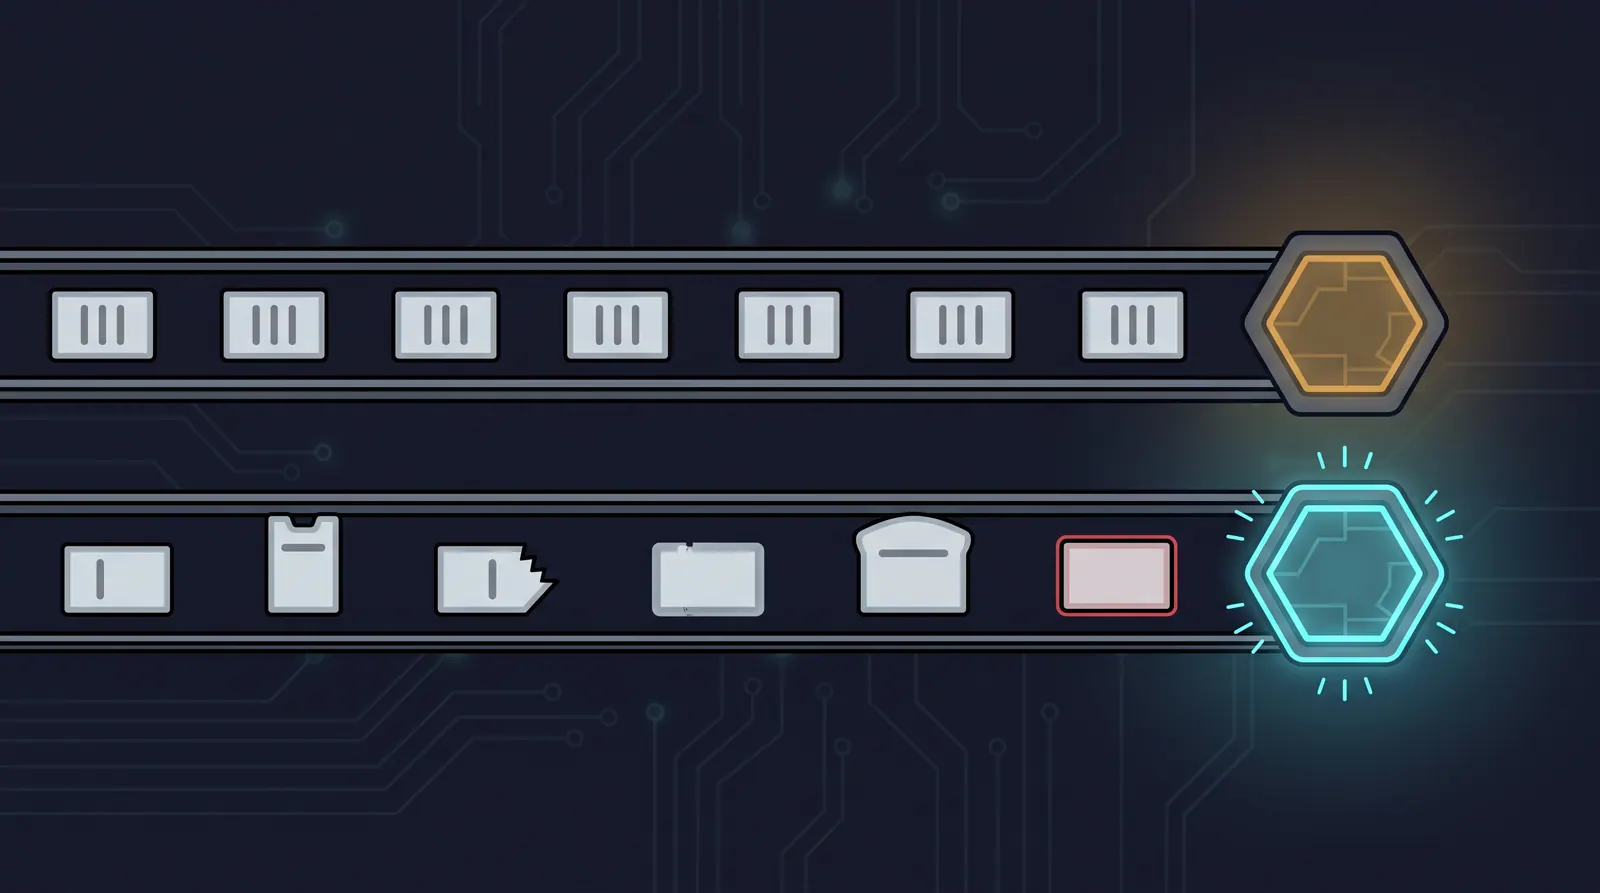
The claim is that it increases coverage with minimal effort. What it reliably increases is the number of executions. Whether any coverage came with them depends on a decision the technique does not make for you.
Look at the rows
Here is the shape of the dataset in almost every tutorial on this, lightly trimmed:
const orderData: Order[] = [
  { user_id: "1", product_name: "iPhone",  product_amount: 500.00,  qty: 1, tax_amt: 5.99,  total_amt: 505.99  },
  { user_id: "2", product_name: "MacBook", product_amount: 1200.00, qty: 1, tax_amt: 12.50, total_amt: 1212.50 },
];
Two rows. Both valid. Both quantity one. Both a product that exists, a user that exists, a total that adds up.
Run that and you have two green tests. You have also tested one thing twice, because nothing in row two exercises a path that row one did not. The second product name is a different string; the code does not care which string.
A dataset earns its place when the rows disagree. Not in their values, in what they force the system to do:
| Row is for | Example |
|---|---|
| The boundary | qty: 0, and the largest quantity you allow |
| The invalid | A product id that does not exist |
| The absent | An optional field left out entirely |
| The awkward | Zero tax, a currency with no decimals, a name with an apostrophe |
| The regression | Whatever produced the last production incident |
Five rows like that are worth fifty of the first kind. And the honest version of the pitch is not “more coverage for less effort” but “the same coverage in fewer lines” — which is a real benefit, just a different one. Fewer lines means less to maintain, and maintenance is where a suite actually dies.
The trap hiding in that example
Look at total_amt again. It is in the input.
The test sends the API a total that the test itself supplied, and then presumably checks that the response contains an order with that total. Which means the assertion passes whenever the API stores what it was given.
A tax calculation bug cannot fail this test. The expected value and the input came from the same place, so there is nothing left to compare against. The test confirms the API can echo arithmetic back.
This is the most common defect in data-driven suites and the dataset format encourages it. Every row is a flat bag of fields, so it is natural to put the expected outcome in beside the inputs, and once it is there nobody notices it arrived from the wrong direction.
The fix is to keep the two apart, structurally, so mixing them requires effort:
const cases = [
  { name: "single item, standard tax",
    input:  { product_id: "1", qty: 1 },
    expect: { total_amt: 505.99 } },      // computed independently, not echoed
  { name: "quantity multiplies before tax",
    input:  { product_id: "1", qty: 3 },
    expect: { total_amt: 1517.97 } },
];
Now expect is an assertion about behaviour rather than a copy of the request. The second row also does something the first cannot: it tests that quantity is applied in the right order relative to tax, which is exactly the arithmetic a flat happy-path row was hiding.
Where does the independent number come from? A spec, a finance team, a hand calculation, or a previously verified response. What it must not come from is the same expression the implementation uses.
Name every row, or a failure tells you nothing
Small point, disproportionate cost.
A loop that produces five tests called create order gives you a report in which one of them is red and no indication which. Somebody then runs the loop with a console.log to find out.
Put the identity in the title, and put it there in a form that survives a reorder:
for (const c of cases) {
  test(`create order — ${c.name}`, async ({ request }) => { … });
}
Not the array index. Indexes shift the moment somebody inserts a row, and a failure history that points at “case 3” stops meaning anything the first time the dataset changes.
Rows must not depend on each other
The other failure that arrives with scale. One row creates an order, a later row assumes that order exists, and everything works until the day the suite runs in parallel or somebody reorders the array.
Then it fails intermittently, and it looks like flakiness rather than what it is — a dependency nobody wrote down.
Each row should set up and tear down what it needs. If that is expensive, the answer is a fixture shared by all of them, not a chain where row two inherits row one’s leftovers.
Where the data should live
The tutorials keep the array in the test file, and for a handful of rows that is right: the data is next to the assertion that uses it, and both are in code review together.
The pull toward external JSON or CSV arrives when non-engineers are meant to add cases. That trade is real but it is worse than it looks — the data leaves version control review, loses its types, and a malformed row now fails at run time instead of at compile time. Take it deliberately, not by default.
Either way, keep the data typed. A type Order on the array is what turns a mistyped field name into a red squiggle rather than a puzzling 400 in CI, and it costs one line.
When a loop is the wrong shape
The technique gets over-applied, and the signal is easy to spot once you know it.
If the rows need different assertions, a loop forces them into one body, and the body grows branches:
if (c.shouldFail) {
  expect(res.status()).toBe(422);
} else {
  expect(res.status()).toBe(201);
  expect(res.body.total_amt).toBe(c.expect.total_amt);
}
That is two tests wearing one costume. The conditional makes the assertion harder to read than either test would have been separately, and it is now possible for a row to take a branch nobody intended — a missing shouldFail flag silently routes an invalid payload into the success path and asserts a 201 that never arrives.
Parameterise the data, never the assertions. When the expected behaviour differs in kind rather than in value, write two loops or two tests. The rule of thumb: if the test body needs to know which row it is running, the rows do not belong together.
The check to run on your own dataset
Open the largest one you have and ask two questions.
Delete any row and does a real bug survive? If the answer is no for most rows, they are duplicates of each other and the suite is slower without being safer.
Where did each expected value come from? Anything derived from the input is not an assertion. That is the row that will be green through the incident.
Data-driven testing is a good technique that gets sold with the wrong number attached. It buys concision, and concision buys maintainability. Coverage still has to be designed one row at a time, and no loop will do it for you.